Jev-X · Why I’m building it
Why I’m Building Jev-X
I believe decision models are worth following, and I want to make meaningful developments around Jev easier to discover.
I’m building Jev-X because of a belief about technology and a very practical frustration.
I believe the approach to decision models that Jev represents deserves serious attention. At the same time, discussions about it are scattered across X, and keeping up with its progress takes a considerable amount of time.
These two things became the starting point for this project: follow a direction I believe in, gather information worth reading, and share it with others who care about it.
Why I’m interested in decision models
LLMs have already shown remarkable capabilities. They can write articles, explain concepts, generate code, and help us organize complex information.
But we still encounter a problem when using them: when context is missing or the evidence is insufficient, they can produce answers that are fluent and complete but inaccurate.
We have to keep checking, separating claims supported by evidence from those that merely sound plausible. Answers are becoming easier to obtain, but judging whether we can trust them still takes effort.
This is one reason I’m interested in Jev.
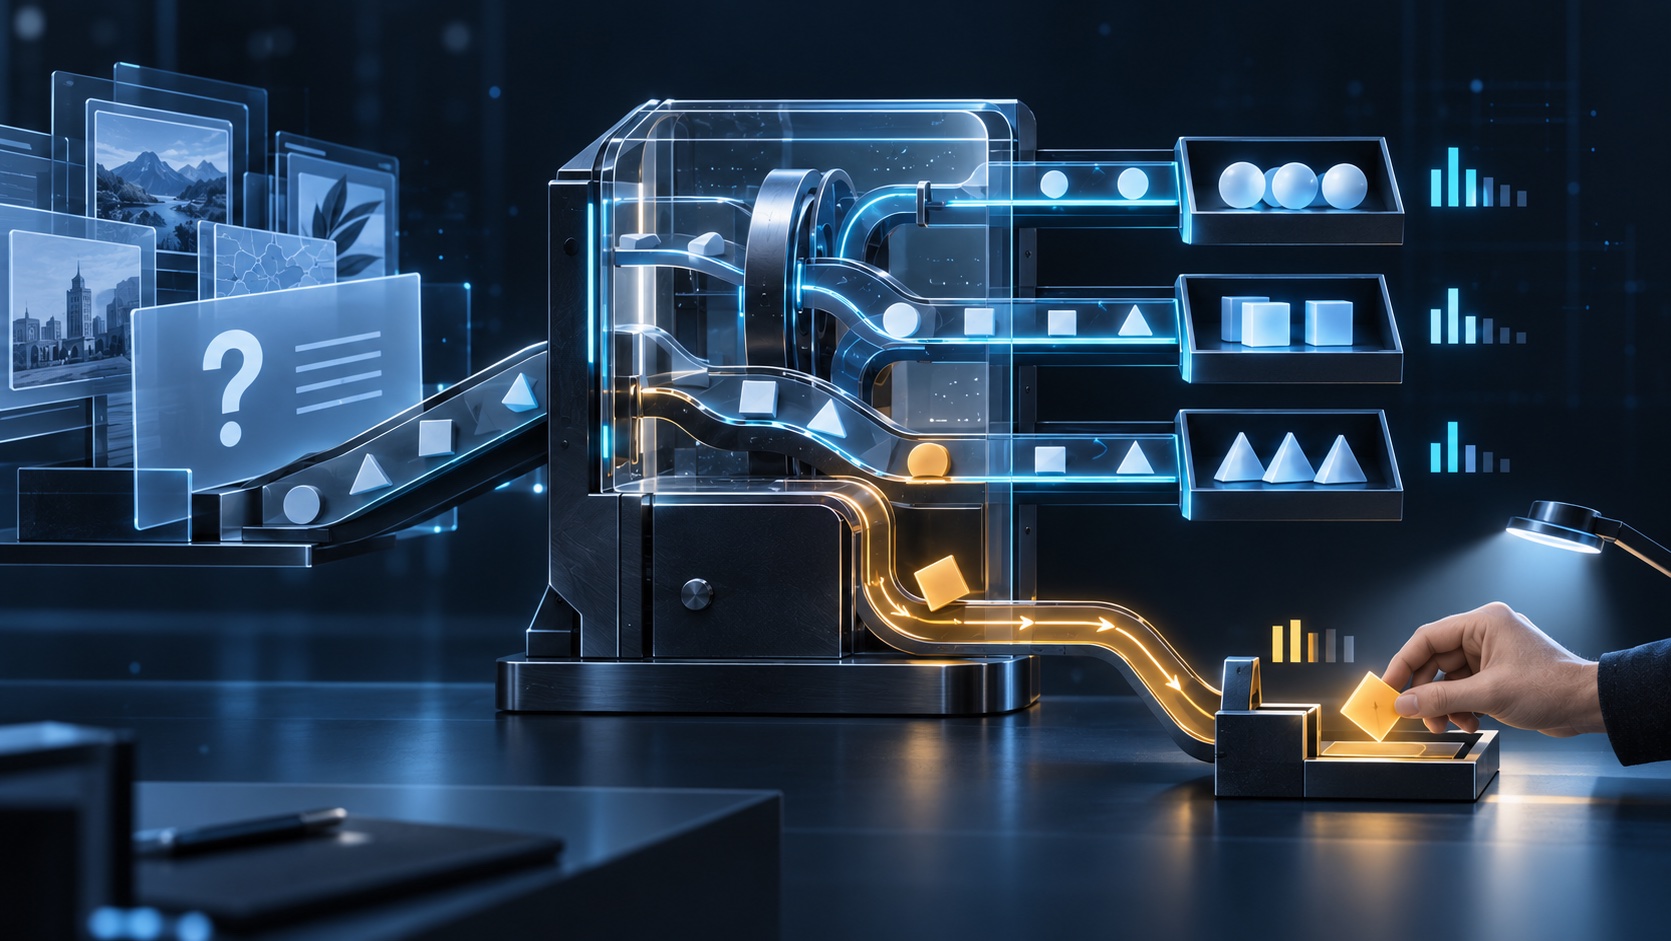
According to TypeSafe, Jev is designed for specific decisions in software: give it a state and a question, and it returns a structured result that a program can use directly, along with probability distributions and confidence for decisions such as classification and scoring.[1]
I see an approach worth exploring here: make a decision explicit, make its uncertainty visible, and give software a way to decide what to do next.
For example, which category should a piece of content belong to? Does it contain useful information? Is the result clear enough to act on, or is more information or human review needed?
Of course, structured outputs and confidence do not mean every decision will be correct. A system still needs to be evaluated for the specific task. Their value is in making uncertainty a signal that software can process and use to choose its next action.[2]
I believe in this direction. A model’s value can show up in well-written content, and it can also show up in the specific decisions that software makes every day.
A single decision may seem small, but when it is repeated at scale, reliability, speed, and cost become important. As more developers experiment and more real examples emerge, I believe the potential of this approach will become better understood and tested in practice.
I want to follow that process from now on: pay attention to new experiments, their actual results, and the limits of what the model can do. Understanding what it can change means looking closely at these developments in practice.
Why turn this into Jev-X?
Trying to follow a direction over time quickly brings up another problem: there is too much information, and our attention is limited.
X has an enormous amount of new content every day. New products, trending topics, opinions, and arguments constantly compete for our attention. We can read a lot and still miss the developments we actually care about.
An important update, a thoughtful evaluation, an inspiring open-source tool, or an experimental application that has received little attention can all disappear into the feed. Finding them again later takes more time.
That’s why I want to build Jev-X and gradually bring this worthwhile content together.
I hope it will help people find important Jev updates, tutorials, open-source projects, hands-on evaluations, and application examples more easily. I also want useful posts from smaller accounts to have more opportunities to be seen.
Popularity can help us discover a topic, but when reading these posts, I care more about the concrete information they offer: what did the author actually do? What were the results? What clues did they share that others can explore further?
Collecting this content over time has another purpose. A single post is only a fragment. Connecting experiments across time helps us understand more clearly how a technology is developing.
Starting with a specific problem
In this project, I also use Jev to classify relevant discussions and score how much useful information they contain, helping me select what to include.
This is a practical experiment: use the model I’m interested in to tackle the problem of organizing information in my own work, then keep learning about its capabilities and limits through actual use.
A score is one clue. Understanding what makes a piece of content worth reading still requires returning to the original post. I hope this work can help people find a starting point faster and then form their own judgments.
I’ll keep improving the project: make the categories clearer, make useful content easier to discover, and adjust the selection process based on feedback from actual use.
I hope to reduce the chances of missing important information, so more of our limited attention can go toward progress worth understanding.
This is the starting point for Jev-X: I believe in this direction, and I’m willing to spend time finding meaningful developments, following them, and sharing them with others who care.